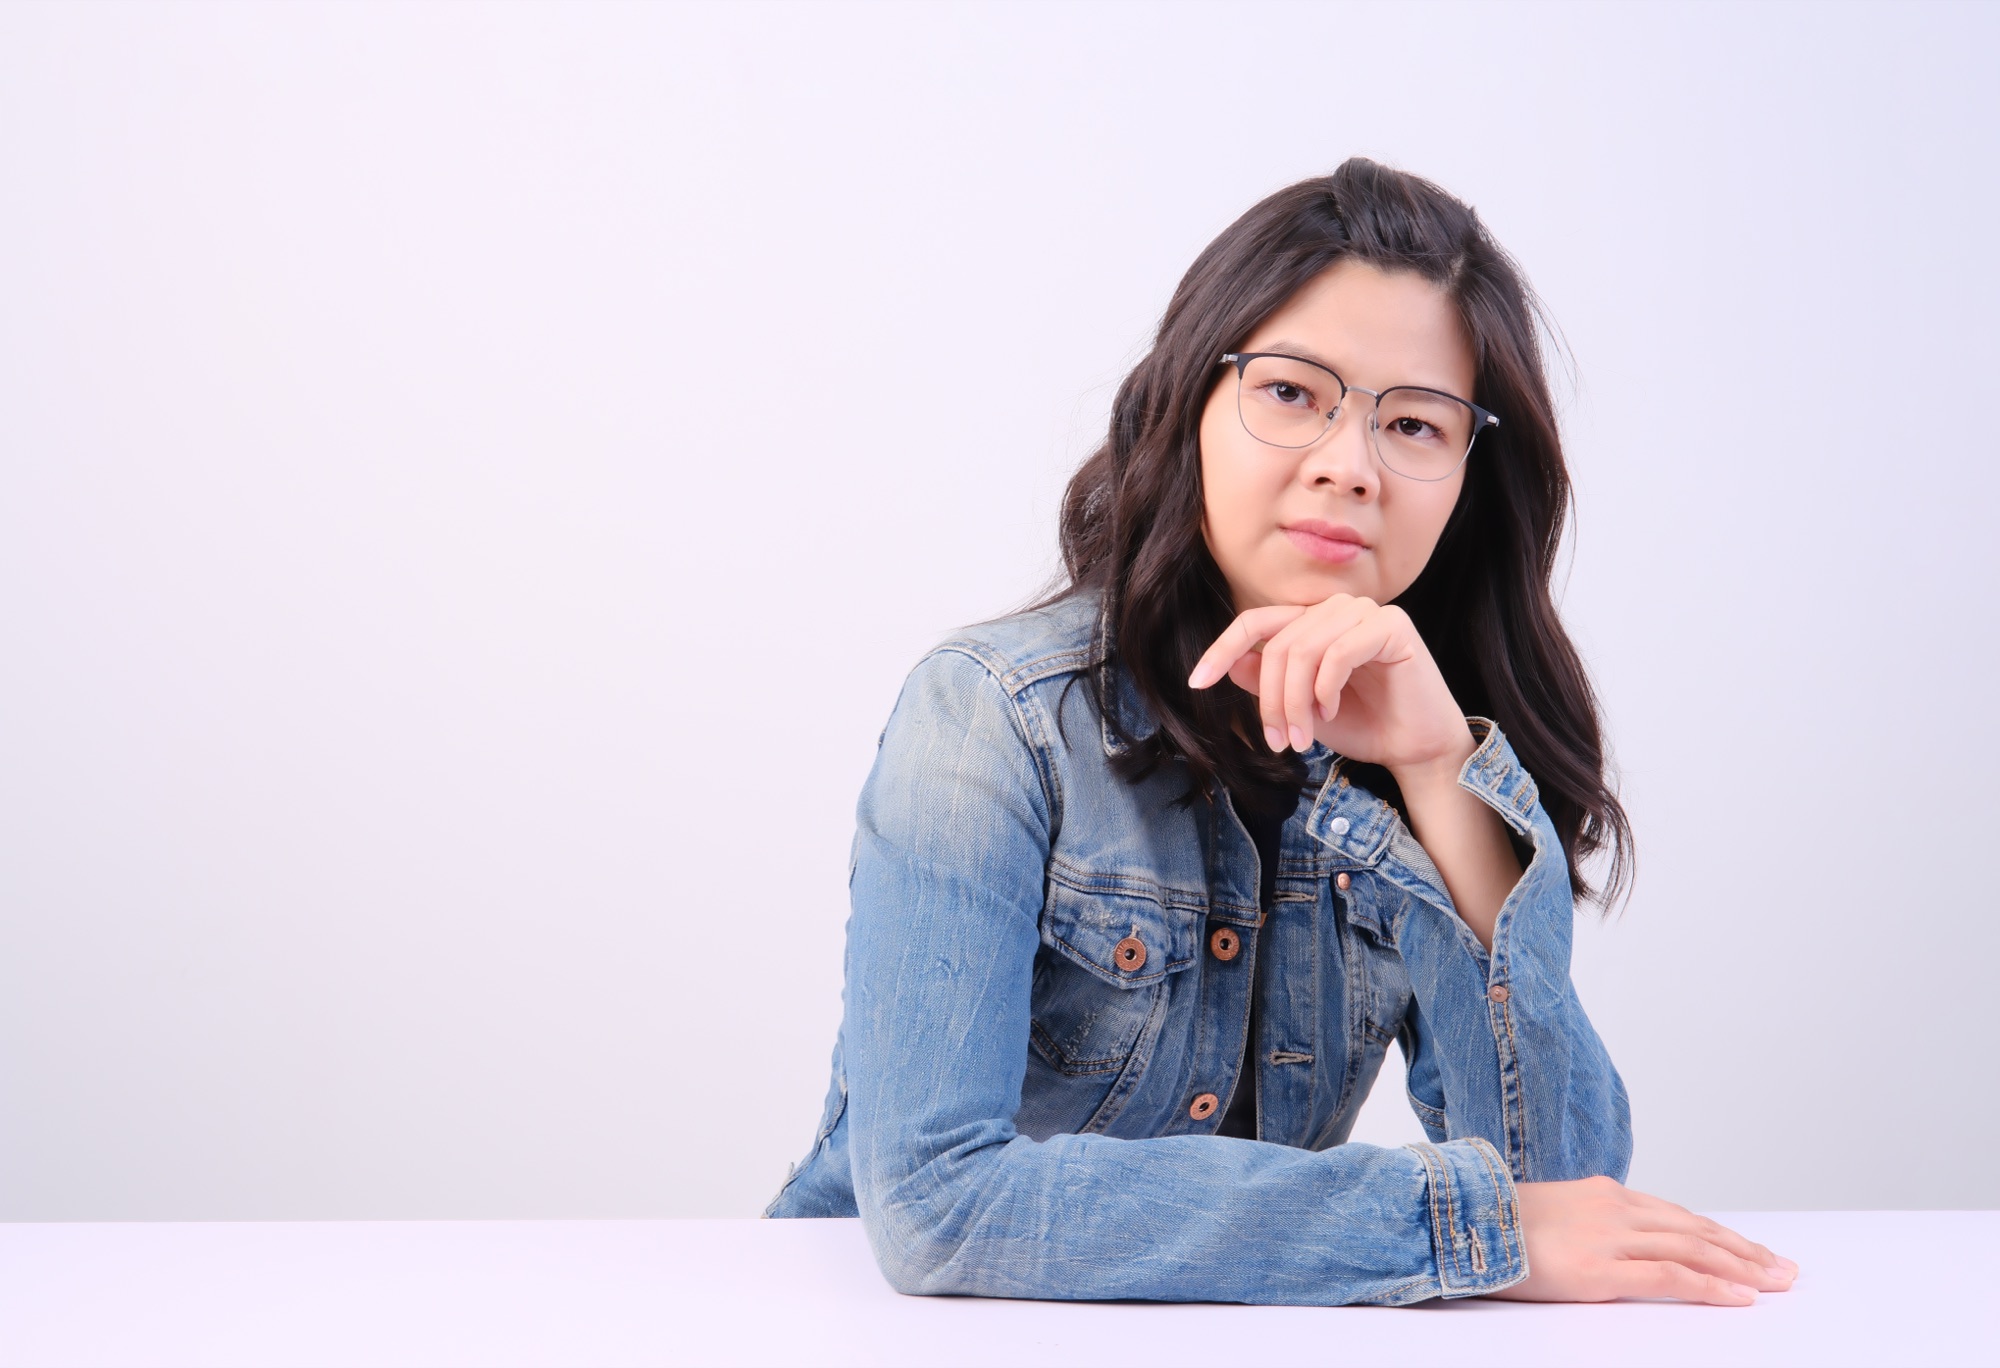
Jia Lin Cheoh seated at a table in a denim jacket, chin resting on her hand.

Purdue University · Next AI

Jia Lin Cheoh

Machine Learning Engineer & AI Researcher

I build AI systems that find and fix their own weaknesses, and I study how people decide whether an AI's output is good enough to accept. Ph.D. candidate at Purdue, where I research artificial intelligence, and founder of Next AI, whose self-improving agents serve 1,000+ enterprise clients.

Selected impact

Numbers from Next AI's production systems.

1,000+
Enterprise real estate clients served across Southeast Asia by the Next AI platform.
+23%
Multi-step task completion from aligned agentic systems with tool use, retrieval, memory, and test-time planning.
87%
Regressions caught before shipping by the evaluation stack that gates every release.
40%
Training time after system-level profiling and custom CUDA kernels across TPU and GPU clusters.

Experience

A company and a research lab, working the same problem from opposite ends.

2013 – Present

Founder & Machine Learning Engineer · Next AI

Founded the company and set its research direction, from post-training through low-latency serving. The platform now serves 1,000+ enterprise real estate clients across Southeast Asia.

Recursive self-improvement

A loop that mines its own failures

Automated verifiers mine production traces for model weaknesses, turn them into targeted eval suites, and feed critique-and-revise cycles back into training. Task success rose 18% over four rounds.

Agentic systems

End-to-end real estate workflows

Designed and aligned agents with RLHF/RLAIF, tool use, retrieval, memory, and test-time planning. Multi-step completion up 23%; 12 client workflows automated with no human intervention.

Evaluation

The stack that gates every release

Extends SWE-bench, τ-bench, and LM Evaluation Harness with domain benchmarks for planning depth, tool-invocation precision, step-level hallucination, and multi-step reliability. Catches 87% of regressions.

ML systems

Distributed training and inference

Engineered training and serving across TPU and GPU clusters in JAX and PyTorch FSDP. System-level profiling and custom CUDA kernels cut training time 40%.
2023 – Present

AI Researcher, Alignment & Evaluation · Purdue University

Studies of how people evaluate AI output, and of what they do once they have it.

Human verification

People run the code instead of reading it

Showed that users verify AI-generated software by executing it rather than reading its source. Broken code still gets approved as long as it runs. Under review.

Acceptance modeling

Why people pick the novel answer

In a mixed-effects regression over human acceptance decisions, lexical novelty raised selection odds 17% and semantic distance lowered them 8%. What people adopt and what they rate highly come apart.

Peer-reviewed

Two published studies

AST-based static analysis of bug and fix patterns in Python data science code (ACM FSE 2025), and CREATIVE-DB, a validated rubric for scoring student-generated work (ACM SIGCITE 2025).

Research & publications

What people do with AI output once they have it.

  1. Under review
    ACM CHI

    Title omitted for anonymity while under review

    A study of how people verify AI-generated code. Details will be posted after the review cycle.

  2. In preparation
    Target ACL / CHI

    Title omitted for anonymity while under review

    A study of how people decide to accept AI output. Details will be posted after submission and review.

  3. Published
    ACM FSE 2025

    Towards Understanding Fine-Grained Programming Mistakes and Fixing Patterns in Data Science

    AST-based static analysis that mines fine-grained bug and fix patterns in Python data science code.

  4. Published
    ACM SIGCITE 2025

    Assessing Student Creativity in Computing Education: The CREATIVE-DB Rubric for Student-Generated Database Problems

    First author. A validated rubric for scoring student-generated work.

  5. In preparation
    Target NeurIPS / EMNLP

    Recursive self-improvement, agentic evaluation, and judge-human alignment

    Papers in progress on the Next AI loop and the Purdue rater studies.

Technical stack

The tools behind the numbers above.

Research

Recursive Self-ImprovementAgentic AIReinforcement LearningModel Evaluation & BenchmarkingHuman-Centered AIRLHF / RLAIF

ML systems

PyTorchJAXFlaxPyTorch FSDPMegatron-LMCUDATritonTensorRTTPU/GPU ProfilingSlurmDistributed Training

Languages & tools

PythonC++JavaSQLGitGCPAWS
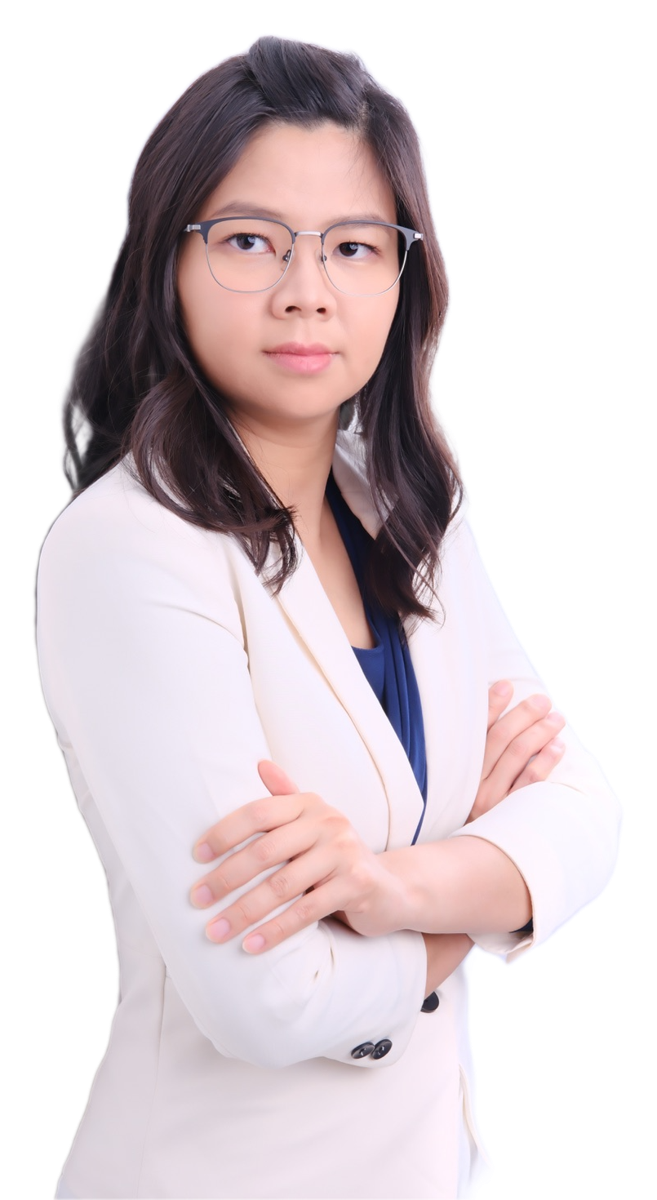
Jia Lin Cheoh standing with arms crossed, wearing a cream blazer.

About

I work on both sides of the evaluation problem.

I am a Ph.D. candidate at Purdue University, where I research artificial intelligence, finishing in December 2026. I was a finalist for the Charlotte W. Newcombe Dissertation Fellowship in 2025 and for the Quad Fellowship in 2024 and 2025.

Before Purdue's doctoral program I completed an M.S. in Computer Science at the University of Illinois Urbana-Champaign with Highest Distinction, Stanford's Artificial Intelligence Professional Program, and a B.S. in Computer Science at Purdue.

Outside research I served as DEI Chair of the Purdue Graduate Student Government and Director of Outreach for the National Association of Graduate-Professional Students, taught as a cybersecurity lab instructor, and mentored in the Summer Undergraduate Research Fellowship.

  • Ph.D., AIPurdue University · Dec 2026
  • M.S., CSUniversity of Illinois Urbana-Champaign · 2026
  • AI ProfessionalStanford University · 2026
  • B.S., CSPurdue University · 2020

If you work on evaluation, agents, or how people judge model output, write to me.